
A beginner can build an AI application by choosing one useful task, selecting a suitable model path, and testing it with real-world cases. A small, focused project can start with an API or visual builder, while a custom model takes more technical work. The right first step is a problem your user already faces, not a fashionable tool.
This guide offers a practical path from defining the task to improving the finished product. You will consider the user, the needed software, and how much time the project may take. A first version can be simple, as long as it solves a real problem and gives people a clear way to check its results.
Key Takeaways
- Choose one task that matters to a real user.
- Test a pretrained model before planning custom training.
- Use examples that match the work your app will receive.
- Give people a way to review uncertain results.
- Keep improving the software after its first release.
AI apps can sort documents, draft text, or spot patterns. First, it helps to see which tasks fit the technology.
What Can an AI App Actually Do?
A fixed form follows programmed rules, while an AI app can classify an unfamiliar document by using patterns in data. AI is useful when software needs to interpret, predict, or create, rather than follow one fixed path.
Inference is the step in which a trained model uses new input to produce a prediction or response. In practice, a user might submit a question, image, or file, and the app returns an answer or label. That result is useful only when the app gives people a way to review it.
AI fits tasks that need interpretation or prediction, while fixed rules handle predictable steps.
Common use cases include routing customer questions, extracting dates from forms, generating images, suggesting products, and forecasting demand. A team might use a model to send billing questions to the right group. A shop might use recommendations to help users find products based on past choices.
Image generation and face identification are different tasks. An AI-generated image of a fictional character does not identify a real person. To create your own AI model girl, you could use a portrait-generation feature to make a fictional character. You do not need to train a new model for that use case.
Choose a task with a clear output, such as a document label or a short summary. Some tasks, like demand forecasting, need a history of sales and a clear time period. Others, such as drafting an image prompt, need a review step more than a project-owned training set.
Useful use cases start with a real need, not a long feature list. Once you see what an app can do, you can choose a problem with a measurable outcome.
How Do You Scope a Beginner AI Project?
Start with support staff spending time routing repetitive questions. A narrow task gives your software a clear job and helps you decide whether it works.
Write down the user, input, expected output, and what the AI must not do. For this project, the user is a support worker, the input is a customer message, and the output is a suggested category. The AI must not send replies or make account changes.
Check the current process before you set a target. If staff already route ten messages in fifteen minutes, record that baseline. A useful target might be fewer minutes per batch, while keeping a person in charge of unclear cases.
Use these scoping checks before choosing tools:
- Who has the problem, and how often does it occur?
- What input will the system receive?
- What output should it return?
- How will a person check uncertain results?
- What measurable change would count as useful?
Keep the first project small enough for one team to test. A support group could start with three common question types, then add more only after the first labels prove useful. Include an “uncertain” option so the system does not force a guess.
Define success in terms your business can observe, such as fewer minutes spent sorting each batch. Accuracy matters, but it is not the only measure. A fast label that staff must constantly correct may not improve the process.
When the task, user, and target are clear, they become the criteria for choosing a development path.
How to Build AI Software: Which Development Path Fits?
A small team can use an API to add a language feature without training a model. Start with the simplest path that can meet the task and success target you set.
Choose a path based on your skills, timing, and need for control. Each option can produce a working solution, but the amount of code and room for customization differ.
Match the build path to the project
An API connects your app to a pretrained model through a programmatic connection to an AI service. A visual builder uses drag-and-drop steps to assemble a workflow. Code-based development gives a team more control, though it calls for programming skills.
| Path | Coding needed | Control | Typical fit |
|---|---|---|---|
| API-based path | Low to moderate | Moderate | Quick integration |
| Visual-builder path | Moderate | Moderate | Rapid prototypes |
| Code-based path | High | High | Specialized or highly customized software |
For example, an API can help a small team add question summaries to an existing support app. A visual builder may suit a simple form that sorts requests. Software development with custom code can fit a product with special rules or several connected systems.
How to build AI software from scratch can mean coding the application around an existing model. It does not always mean training a large model from the beginning. A model service can handle inference while your code manages the user experience and business rules.
Keep the first choice reversible
You can begin with an API or visual builder, then move to custom code if the first version cannot meet new needs. Keep the early design simple, and avoid tying every feature to one hard-to-change workflow. This approach gives the team room to learn from actual use.
Once the build path fits the project, decide whether the task needs an existing model or a model developed for it.
Should You Use a Pretrained Model or Train One?
Most first projects should test an appropriate pretrained model before considering custom training. Test first, because an existing model may already handle the task well enough.
Use the least model work that meets your measured need. An API project may call a pretrained model without training one. Fine-tuning adapts a model with additional examples, while custom training develops and trains a model for a specific project.
Start with a pretrained model
A pretrained model has already learned general tasks from earlier training. You provide input and build the app around its response. It often suits early tests, though you still need to check output quality for your users.
Deep learning is one approach for learning complex patterns from data. It is not a required step in every AI project. A simple app may use a model service, fixed rules, or both without any model training of its own.
| Model approach | What you change | Data need | Typical reason to choose it |
|---|---|---|---|
| Pretrained | Use the model as provided | Task inputs and review examples | Test a common task quickly |
| Fine-tuned | Adapt an existing model with examples | Labeled examples for the task | Improve fit for a repeated task |
| Custom-trained | Develop and train a project model | A suitable project dataset | Meet needs existing models cannot meet |
Train or fine-tune only when needed
Supervised learning uses labeled examples. Unsupervised learning looks for patterns in unlabelled data. Reinforcement learning uses feedback to shape action choices.
These methods ask for different data and effort. Fine-tuning can help when a model misses important patterns in your examples. Custom training may offer more control, but it needs the right data, skills, and computing resources.
People may search for ways to create your own AI model for free. Free software or model access does not make data, computing, and hosting free. Start with what your project can support, then compare the results with your target.
Any choice to train or fine-tune depends on having suitable data for the task.
What Data Does Your AI Need?
A document-classification app needs examples that match the documents users will send. Representative data helps show whether the model can handle real inputs, not just tidy samples.
Use data that fits the task, and check its rights and quality before use. An API-based app with a pretrained model may need little project-owned training data. It still needs checks for user inputs and model outputs.
Possible sources include internal records, open-source datasets, and paid third-party datasets. A public set may not reflect your users or current documents. A dataset search can help you compare options, including licensing, bias, and how recently examples were collected.
Prepare project data with these steps:
- Find sources that include the inputs your app will receive.
- Check rights and permissions before using each source.
- Remove duplicates, correct errors, and standardize formats.
- Label examples if the task needs labeled data.
- Separate training, validation, and final test examples.
A proprietary model workflow often uses separate training, validation, and test sets. Training examples teach the model, validation helps guide changes, and test examples check the final result. Keep the final test set apart until evaluation.
When personal details are not needed, anonymization can remove identifying details from examples. For a support classifier, that may mean replacing a customer’s name with a neutral label. Keep only the data the task needs, and check that the change does not remove information essential to the output.
For practical dataset guidance, see how to find and use machine-learning datasets. Prepared data and a selected model now point to the tools and environment needed to build the app.
Which Tools and Languages Should Beginners Learn?
Learn only the language and tools needed for the first working version. Keep the toolkit small instead of trying to master an entire AI stack.
Python is a common starting language for AI and data work. JavaScript suits web apps, and R is used for statistical analysis. The best language depends on the app you are building and the tools your team already knows.
Pick a language around the application
| Language or tool | Common use | Beginner fit |
|---|---|---|
| Python | AI and data work | Good for scripts and model tasks |
| JavaScript | Web applications | Good for interactive web features |
| R | Statistical analysis | Good for data analysis tasks |
| TensorFlow or PyTorch | Machine-learning development | Useful when building or training models |
TensorFlow and PyTorch are machine-learning frameworks, which are tools for building and training models. You do not need them just to connect an API or test an app. Start with one tool that helps you finish the first feature.
Check what your computer can run
How to make an AI on your computer depends on the task and available hardware. A small script or API-connected app can run locally. Training large deep-learning models may need substantial computing resources or cloud infrastructure.
Advanced math is not a prerequisite for connecting an API or assembling a simple app. Probability and statistics help as you measure results. Linear algebra and calculus become more useful when your model development gets deeper.
Do not install every tool you find in a tutorial. Pick a language that fits your application, then add tools only when the task calls for them. A beginner building a web feature may need a browser, an editor, and an API account, not a full machine-learning setup.
Once you have chosen the tools, requests and model calls need a place in the application backend.
How Does AI Work in the Backend?
A user submits a question in a chat box, and the app returns a model-generated response. The backend manages the request between the user interface and the model.
The backend checks input, sends it to a model, handles the result, and returns a usable response. The model supplies one part of the feature. The surrounding software makes that response fit the application.
First, the app validates the question, such as checking that it is not empty. The backend then sends the input to a model or model service. After the model replies, the app handles errors and returns a result the user can understand.
The backend can apply rules around the model. It might limit input size, reject unsupported file types, or require a human check before an answer reaches a customer. These rules protect the application from relying on a response that is incomplete or unsafe.
For example, a support tool could show a suggested answer for staff to review. The model generates text, but the software controls who sees it and whether it can be sent. If a model call fails, the app can show a retry option rather than a blank page.
This flow separates the model’s response from the rest of the system. A response may need formatting, context, or a warning before it becomes a useful app feature. The backend also tracks whether the call worked and what happened when it did not.
From this request flow, the next step is integrating it into a complete application.
How Do You Connect the Model to an App?
A user who uploads a document expects a useful summary, not raw model output. Build the full feature around that expectation, from the upload screen to the final response.
A front end handles what users see, while a backend manages model requests and app rules. The front end accepts a document and displays a clear status. The backend checks the file, calls the model, and prepares the summary.
Build the interface and backend
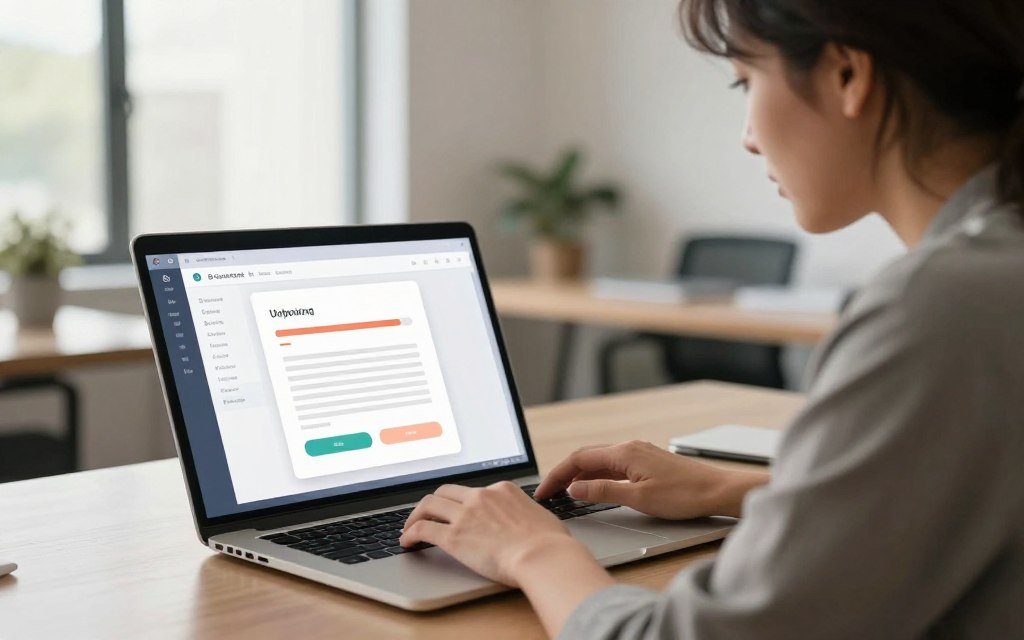
For a text summarizer, the interface should say which file types it accepts. The backend should enforce input limits and reject empty or unsupported files. After processing starts, a loading state tells users the app is working.
Use plain labels for the result, such as “Summary” and “Try again.” Give users a way to compare the summary with the original document. Clear context also helps the model return a focused response; a guide to asking clear AI questions explains how context can improve answers.
Handle model responses and failures
The app must handle malformed or empty responses. It should also respond to timeouts, when a model call takes too long. Offer a retry option, or route the document to a person when a summary cannot be returned.
Keep the model response separate from the app’s presentation. The backend can check whether required fields exist, then show only the content the user needs. If the result is uncertain, the interface should say so rather than presenting a guess as fact.
An API connection alone does not make software ready for real users. The app still needs clear limits, failure handling, and a simple way to recover. The same is true when an app uses several tools to act on a user’s behalf.
That leads from a single AI feature to an agent that can choose among bounded actions.
How Can You Build a Basic AI Agent?
A chatbot answers a question, while a bounded assistant can draft a calendar action for approval. Keep its choices limited so the agent can only take actions you permit.
An agent is a model-powered workflow that selects from permitted tools or actions to complete a task. A meeting assistant might summarize notes and draft follow-up tasks, but ask before sending messages.
Define tools, actions, and limits
Give each tool one clear purpose, such as finding a free calendar time or drafting a message. Do not expose unrelated tools. The agent should not send a message just because it can draft one.
A controlled build sequence can help you keep its work within bounds:
- Define one task the agent should complete.
- Expose only the tools needed for that task.
- Set permission limits for each action.
- Test allowed and disallowed actions.
- Require human approval for consequential actions.
Build a controlled action loop
The agent receives a request, selects an allowed tool, and returns a result. Your application checks the choice before running the tool. If the action needs approval, the system pauses and asks a person.
For a meeting assistant, the model could turn notes into draft tasks. A person can edit the list before the app creates calendar events. Sending a message or changing a shared schedule should require a clear approval step.
How to build agentic AI for free depends on access to models and tools. Free access may help with a prototype, but it may not cover hosting or ongoing use. A small test with limited actions can reveal whether the workflow helps before you add more tools.
OpenAI’s guide to building agents also describes tool limits and human review. Next, test both the agent’s outputs and its behavior when inputs or actions go wrong.
How Should You Test AI Outputs?
Start with a test case where you already know the correct output. Known answers let you compare the model’s response with something concrete.
Test typical requests, unusual inputs, and failure paths before launch. Review results against an accepted answer or ask a person to check them when judgment matters.
Keep a record of test results and note which cases the app handles poorly. For a support router, a message clearly asking about a refund might have one expected label. A vague message may need a human review instead.
Use this checklist to cover more than routine requests:
- Expected cases with a known correct answer.
- Unfamiliar examples the model may not have seen.
- Edge cases, such as empty or unusually long inputs.
- Unsupported requests the app should refuse or redirect.
- Consistency across repeated runs and response time.
- Fallback behavior when the model or network fails.
Model outputs can vary across repeated runs, so check whether changes affect the result. Record response time as well as correctness. A slow answer may make an otherwise accurate feature hard to use.
When training is involved, keep test data separate from training data. Validation helps reveal overfitting, which happens when a model fits training examples but struggles with new ones. Compare the model’s work with a human review where the task needs judgment.
Testing shows how the feature behaves, but real user inputs also raise questions about privacy, security, and responsible data handling.
How Do You Protect Privacy and Meet Compliance Needs?
A small customer-support tool may receive names, order details, and other personal information. Plan before launch so the app handles those details only as needed.
Privacy safeguards and legal compliance are related, but they are not the same. The rules that apply depend on the product, data, users, and jurisdiction. A careful design still needs a review of the relevant laws.
Protect data through its lifecycle
Collect only the data the task needs, and make sure you have permission to use it. Limit who can access sensitive inputs. Protect stored data and information sent between systems, then set a retention limit for data the app no longer needs.
Tell users when they are interacting with AI. Explain what the feature does and where a person can help. Clear language gives users a better sense of when an answer came from a model.
Review fairness, transparency, and security
Check whether the model treats similar users in different ways without a good reason. Document important choices about the model and data, so your team can review them later. Keep security and fairness checks part of the product process.
Use this checklist before the app handles real user information:
- Identify personal and sensitive inputs.
- Limit access to people who need it.
- Disclose when users are interacting with AI.
- Review outputs for unfair patterns.
- Document model and data choices.
- Determine which rules apply to the product.
GDPR, CCPA, and the EU AI Act are examples of regulatory frameworks that may matter for some products. Their rules differ by context and location. This overview is not legal advice; a qualified legal professional can help assess a specific product.
Once safe design decisions are in place, choose a deployment environment and plan a controlled rollout.
How Do You Deploy an AI App?
Release a tested AI app to a small group of intended users before opening it to everyone. A pilot gives the team a chance to see how the application works in real use.
Deployment means setting up access, configuration, and model connectivity for a controlled release. The right environment might be cloud infrastructure, private infrastructure, or a mobile app release.
Before the pilot, set up the app’s configuration and access controls. Check that it can connect to any model services it needs. Keep the release limited to the people who will use the feature and report problems.
For a support tool, you might start with one team and one type of question. That lets the team learn whether the feature fits the work before more users depend on it. A narrow release also limits the impact of a broken feature.
The app should handle model or network failures without exposing sensitive information. If a request fails, show a clear message and a next step. Avoid displaying raw error details that could reveal private system information.
Deployment involves more than making software available. The app needs a working connection to its model service and a clear way for intended users to access it. A controlled release gives the team a chance to correct setup problems.
Once the release is live, watch performance and user feedback to see what needs attention.
What Should You Monitor After Launch?
A classifier may become less reliable as the types of customer requests change. Watch real use so you can spot problems that did not appear during the first tests.
Technical monitoring tracks errors and latency, while model monitoring tracks output quality and changes in input patterns. Latency is the time a user waits for a result. Both kinds of monitoring help you see how the app performs.
Model drift means the model performs worse when real-world data or behavior shifts from what it learned. For example, a support classifier may see new billing questions after a product change. Track whether staff correct its labels more often.
Review user feedback, usage patterns, failures, and the cost of model calls. A sudden rise in errors may point to a connection issue. A change in input patterns may mean the task has changed or the model needs review.
Do not retrain or replace a model just because the calendar says so. First check evidence from real use. If quality drops, review the examples, fine-tune the model, retrain it, or consider a better fit for the task.
Keep a record of which changes help and which do not. A small review process can catch a problem before users build workarounds. Watch whether the feature still supports the business task it was meant to improve.
Ongoing monitoring also affects realistic planning for project time and budget.
How Much Time and Money Does an AI Project Need?
A simple API-backed prototype can take far less work than a custom model project. Plan by scope, because the time and cost depend on what the app must do.
These broad planning ranges are estimates, not a quote or guarantee. The table compares indicative minimum viable product, or MVP, timelines and costs for three common approaches.
Budget the first usable version
| Approach | Indicative time to MVP | Indicative cost | Common cost drivers |
|---|---|---|---|
| No-code | 1-3 weeks | $0-$2,000 | Premium integrations and platform features |
| Code-based | 2-6 months | $10,000-$100,000+ | Development talent and infrastructure |
| API-based | Days to 2 weeks | $50-$1,000 per month in usage estimates | Ongoing usage and scaling |
The ranges can help a team plan an early discussion, but the project may fall outside them. Data volume and labeling affect the work. So do model complexity, accuracy needs, integrations, security, and real-time processing.
Identify what changes the estimate
How to build AI software free often means starting with free tools or a free tier. Those can help you test a prototype, but data, usage, hosting, and maintenance may still carry costs. A no-cost start does not promise a no-cost product.
API-based development may involve ongoing use charges as more people send requests. A code-based project may need developer time and infrastructure before a user can test it. Premium integrations can add costs to a visual builder as the app grows.
Start by estimating the smallest version that can test the task. Add the features users need, rather than budgeting for every possible use. This makes the main sources of uncertainty easier to discuss with a business or project team.
Planning around uncertainty helps you avoid common first-project mistakes.
What Common Beginner Mistakes Should You Avoid?
It is tempting to start with a fashionable model or tool before confirming the user problem it solves. Begin with the need, then choose technology that fits the task.
A narrow first release with human review often teaches more than a feature-heavy launch. Keep the software small enough to test, and make sure users can flag bad results.
Start with a user problem, test one focused feature, and keep people in control of uncertain outcomes.
Common mistakes can waste time or damage user trust. Pair each one with a clear correction:
- Starting with a model instead of a user problem: write down the task and target user first.
- Assuming more data is always better: choose data that matches the task and check its quality.
- Training a custom model too soon: test an appropriate pretrained model first.
- Launching without unusual-input tests: check empty, unclear, and unsupported requests.
- Letting an agent act without clear permissions: limit tools and require approval for consequential actions.
- Treating launch as the end of development: keep reviewing results and user feedback.
A large dataset can include duplicate, outdated, or unrelated examples. More entries do not help if they teach the wrong pattern. Select data for a clear purpose, then check what the model learns from it.
An agent with access to too many actions can create trouble even when its answers sound sensible. Keep the first action list short, and let a person approve steps that affect other people or shared records.
Expect development to continue after the first release. User needs can change, and a new model response may expose a flaw. Make changes based on evidence rather than adding features to make the app look more advanced.
The best next step is a small, testable task that a real user can review.
Conclusion
A useful first AI project begins with a specific task and a way to tell whether it worked. Focused use and careful evaluation matter more than starting with the most complex model.
Write down one user problem, one expected AI output, and one success measure before choosing a tool. Keep the first version small enough to test with real examples, and give a person a way to review uncertain results.
Your concrete next step is to draft those three project decisions, then test a small prototype with a few realistic cases.

 By
 By